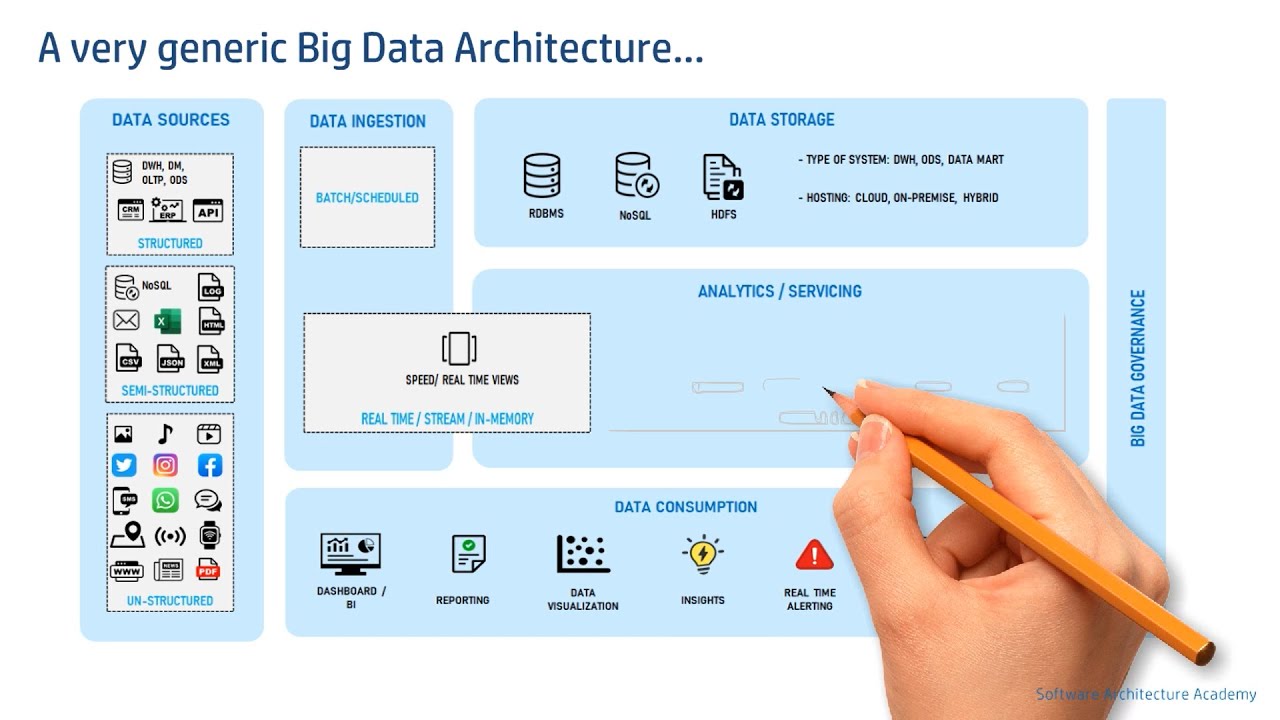
[Music] with this episode of math skills we're starting a series of videos dedicated to architecture we'll start from the ground up the data layer that is if you draw your app architecture with the data layer at the bottom the data layer contains application data and business logic the business logic is what gives value to your app it determines how application data must be created stored unchanged the data layer is made of repositories that each can interact with zero one or more data sources data sources much like their name suggests are responsible for providing data the
app needs to function they may present data from the network a local database files or even from memory and they should have the responsibility of working only with one source of data which typically holds a unit of business logic for example articles users or movies that's data sources now repository classes are used by all the layers in your app to interact with the data layer they are responsible for exposing data to the rest of the app but also for centralizing changes the data resolving conflicts between multiple data sources and containing business logic you should create
a repository class for each different type of data you handle in your app for example you might create a movies repository for data related to movies or a payments repository for payments repositories can combine different data sources and they're responsible for solving any potential conflicts between them if there's a clash between the data in your local database and the server for example the repository should detect and fix this remember that all the layers in your app should never depend on data sources directly the entry points to the data layer are always the repository classes a
common pattern in repositories is to perform one-shot calls like create read update and delete these can be implemented with suspend functions in kotlin but also you can be notified of data changes over time by exposing a data stream for example using kotlin's flow this is out of the scope of this video so if you want to learn more check out our flow guide the link is in the description handling multiple data sources in a repository can get tricky you need to choose a source of truth and make sure that it's always in a consistent state
let's look at a concrete example let's say we have two sources of data for news local news data source depends on a room database and can return a list of articles or update them remote news data source depends on an api client for example a retrofit client this one can only fetch news now the news repository would depend on those two data sources if we want to fetch the news from other layers we use the fetchnews method on the repository this method tries to load the news from the network first if it succeeds it updates
the local database if it fails because there was no data connection or the server was down it just logs the error instead you might want to show something in the ui finally in any case it returns the result from the database since it's our source of truth this case is very simple because we're using data that the user can't edit however resolving conflicts can get challenging for example imagine a calendar app where a meeting is modified by two users at the same time so this will require some thought because getting this right is important for
a good offline first user experience libraries that consume remote apis and remote databases such as file store have caching mechanisms that you can use and they can even deal with conflicts now let's talk about immutability the data exposed by the data layer should be mutable so that all the classes cannot tamper with it this would risk putting its values into an inconsistent state another advantage of immutable data is that it can be safely handled by multiple threads kotlin's data classes are a perfect tool for this by the way when modeling entities you should consider that
the model returned by your database or the remote api might not be what the other layers need for example in this article model if you don't need the modifications or the author's date of birth create a different model for the ui layer this not only makes your code neater it provides better separation of concerns letting each layer define what model it needs let's talk about threading now calling data sources and repositories should be main save save to call from the main thread this means that the repositories or data sources are responsible for moving the execution
of their logic to the appropriate thread when performing long running or blocking operations something else to take into account are errors because data operations won't always succeed it's important to somehow propagate information about a failure to the other layers one option is to simply let exceptions propagate with suspend functions you can wrap repository calls in a regular try catch block from the ui or the domain layer or if you're using flows you can use the catch operator another option is to catch these errors in the data layer and expose data that can contain either a
success or a failure with a more meaningful exception in any case don't forget about dealing with errors they will happen as you saw earlier a repository can depend on multiple data sources in some cases you might want to have multiple levels of repositories this is perfectly fine in this example a user repository needs data from a login repository and the registration repository similarly to repositories can share a data source all these tips are recommendations that should work well in most apps however if you have a reason to deviate feel free to do it finally let's
talk about testing the data layer is typically easy to test repositories are unit tested normally you replace the data sources with fakes or mocks and verify that your repository is correctly handling data and calling the data sources we need it testing data sources can be slightly tricky because they depend on databases or api clients however the libraries that let you do that usually provide test artifacts or mechanisms for testing for example room provides an in-memory database implementation that can help you test the code in the data source in end-to-end or big tests you test all
the layers of your app at the same time but you might want to use fake data to make your tests faster and more reliable if you use dependency injection you should be able to replace data sources or repositories with fake implementations you can also fake your network calls with popular libraries such as wiremock or mock web server this video is a summary of the data layer article in the architecture guide for more details and code samples about best practices in the data layer check out the rest of the guide here and that's it i hope
you learned the difference between a repository and a data source and how to model the data they expose the next video we're releasing is about the ui layer so subscribe if you want to be notified when it's out or if you're from the future check it out next thanks [Music]