[Music] now we go to data science tasks the first is description data scientists are often called upon to describe patterns and trends lying within the data for example a data scientist may describe a cluster of customers most likely to leave our company's service as those with high usage minutes and high number of customer service calls after describing this cluster the data scientist may explain that the high number of customer service calls indicates perhaps that the customer is unhappy working with the marketing team the analysts can then suggest possible interventions to explore to retain such customers
the description task is in widespread use around the world by specialists and non-specialists alike for example when a sports announcer states that a baseball player has a lifetime batting average of 0.350 he or she is describing this player's lifetime batting performance for estimation estimation refers to the approximation of value of a numeric target variable using a collection of predictor variables estimation models are built using records where the target values are known so that the models can learn which target values are associated with which predictor values then the estimation model can estimate the target values for
new data for which the target value is unknown for example the analysts can estimate the mortgage amount of potential customer can afford based on the set of personal and demographic factors this estimate is based on a model built by looking at the past models of how much previous customers could afford estimation requires the target variable be numeric for classification classification is similar to estimation except that the target variable is categorical rather than continuous classification represents perhaps most widespread tasks in data science and the most profitable for instance the mortgage lender would be interested in determining
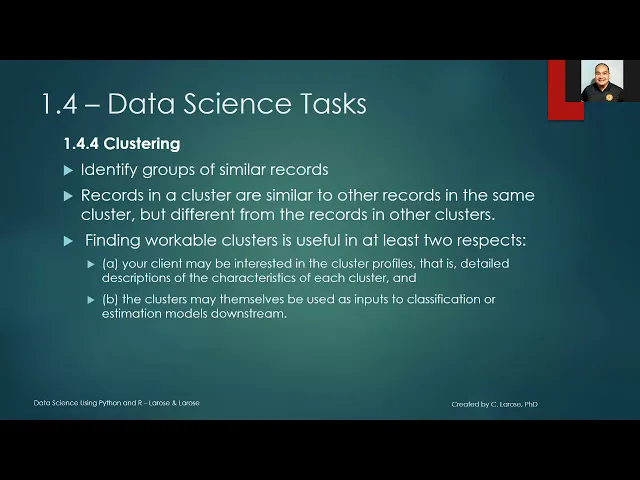
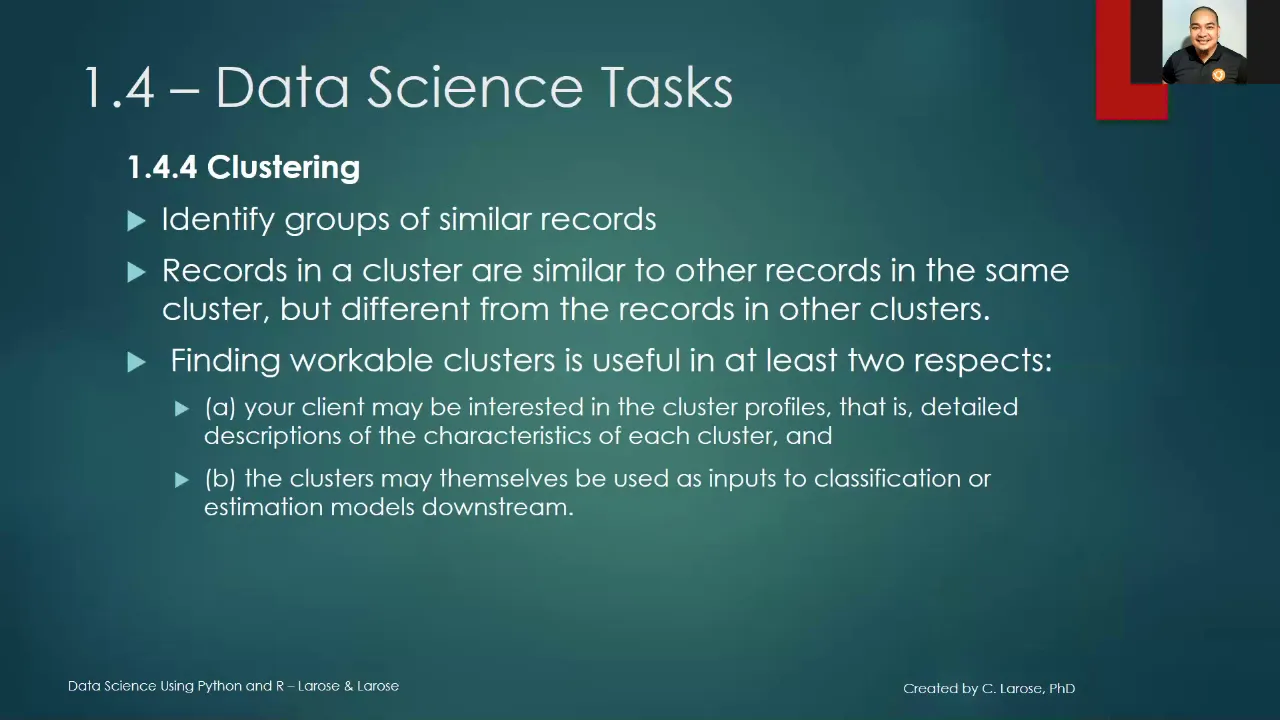
which of their customers is likely to default under mortgage loans similarly for credit card companies the classification models are shown lots of complete records containing the actual default status of past customers the models then learn which attributes are associated with customers who default finally these trained models are then deployed to new data customers who have applied for a loan or credit card with the exception that models will help to classify which customers are most likely to default on their loans next is clustering the clustering task seeks to identify groups of records which are similar for
example in a data set of credit cards applicants one cluster might represent younger more educated customers while another cluster might represent older less educated customers the idea is that the records in a cluster are similar to other records in the same cluster but different from the records in other clusters finding workable clusters is useful in at least two respects one your client may be interested in the cluster profiles that is detailed descriptions of the characteristics of each cluster and second the clusters may themselves be used as inputs to classification or estimation models downstream for prediction
the prediction task is similar to estimation or classification except that for prediction the forecasts relate to the future for example financial analysts may be interested in predicting the price of apple stock three months down the road this would represent estimation since price is numeric variable and prediction since it is related to the future alternatively a drug discovery chemist may be interested in whether a particular molecule will lead to a profitable new drug for a pharmaceutical company this represents both prediction and classification since the target variable is a yes or no variable whether the drug will
be profitable the association task involves determining which attributes are associated with each other that is which attributes go together the data scientist using association seeks to uncover rules for quantifying the relationship between two or more attributes these association rules take the form if antecedent then consequent together with measures of the support and confidence of the association rule for example marketers trying to avoid customer churn might uncover the following association rule if calls to customer service greater than 3 then customer will churn the support refers to a proportion of records the rules applies to the confidence
is the proportion of times the rule is correct [Music] [Music] you