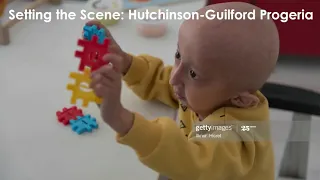
The baby in the picture is suffering from what's known as Hutchinson-Guilford progeria syndrome, which is an extremely rare and progressive genetic condition that produces rapid aging in children. The average life expectancy of the children with the syndrome is known to be 13 years old. In individuals with this syndrome, cardiovascular diseases such as heart failure or strokes are most common causes of death in the teenage years.
As you can see from the picture, the individuals with the disease display very characteristic facial features including the eyes. and the most common ocular manifestations are the prominent eyes, loss of eyebrows and eyelashes, and lagophthalmos, which is the inability to close the eyelids completely. Unfortunately, there is no cure for progeria at the moment but research for treatment is ongoing.
As a part of the ongoing effort, a clinical study in 2012 examined the effect of treatment with a drug called Lornafarnib on a number of physiological outcomes among those outcomes the researchers measured what's called the pulse wave velocity (PWV) of 18 children diagnosed with the syndrome. PWV is often used as a measure of vascular stiffness, which is an important factor in cardiovascular health and it is known that this outcome measure is abnormally high in children with the syndrome. So the objective of the study was to test the effect of the drug in slowing down the outcome measure called PWV.
To that end, 18 children with progeria were recruited and their PWVs were measured at baseline first. Then they received a daily dose of the drop for two years and their PWVs were measured again. so the million dollar question here is to see if on average their treated PWVs were reduced from the baseline measurement when they are compared.
So in this case, the mode of comparison here is within-subject comparison because the PWV measurements before and after for each patient are paired measurements in that those measurements are collected from the same patient and they are compared within the same patient. Therefore we will use a t-test called paired samples t-test accordingly. Before we see the data, we need to set up a pair of hypotheses as usual.
So here the null represents no effect or change in the population mean difference. So the average difference between the PWV at baseline and after treatment will be more or less zero. So this is how we're going to write it.
The population mean of PWV baseline and PWV treated should be more or less zero. So there should be no difference, which will be regarded as a negative evidence of the drug. On the other hand, the mean difference between the PWVs should be different to claim that the drug is effective.
So the mean PWV should be different from zero at least statistically and so this is a two-tailed hypothesis but more specifically the difference should be in the reduction of the treated PWV compared to the baseline PWV, not the other way around. So I mean the two-tailed test will tell you which way the outcome is directed but in one tailed fashion, we can say that PWV baseline minus PWV treated should be what? Should be positive right?
Because it is expected that the PWV at baseline much faster than after they are treated. So these are the two pairs of hypotheses. So the bottom one is one-tailed alternative hypothesis whereas the top one here is two-tailed alternative hypothesis.
So this is the sample of PWV data collected before and after the treatment from the 18 patients. Please note that the unit of the outcome measure PWV is metres per second. Now let's run the descriptive statistics and the paired samples t-test using Jamovi.
So this is the data copied from the slide. Unfortunately you have to actually manually type this data into Jamovi and as there is no excel file to follow what I'm doing. So if you haven't done so, please stop the video and have the data into Jamovi.
So unlike the independent samples t test, we do not have groups to be distinguished. So what you do in a paired samples t-test, you just type all the data, enter all the data from the baseline condition in one column and type, enter the data from treated condition in a separate column because this baseline and treated data are paired if it is on the same row. So you do not have the separate grouping variable but you only have two different variables and then the number of rows should match between these two columns because they are paired.
So let's just take a look at how we run this paired sample t-test by clicking t-test and go to paired samples t-test. We need descriptives and we also need descriptive plot which will be just side by side 95% confidence interval and the mean difference and we like to have the 95% confidence interval too and we're going to just then leave this a two-tailed hypothesis testing as default and for paired sample t-test you need to check the normality of the different score, the difference between baseline and treated. So you to tick this box to check the assumption.
So now you can move baseline first and then treated to make it paired or you can click baseline hold down shift and then left mouse click to select both and move together I mean that's just basically the same but and there are different ways to move paired variables. So let's take a look at the descriptive statistics. So the mean baseline PWV is 12.
4 whereas the mean PWV for treated is 8. 5. It looks like there's a more variability in baseline compared to treated but that is not really relevant in this case because we're gonna, we only need to take a look at the difference between these two and the associated standard deviation of that difference, not the individual PWV conditions on average.
And we're going to talk about this in more detail later on but this is not really right representation of 95% confidence interval for paired samples. Other statistical software including Jamovi or SPSS, they assumed that these two conditions are independent and this side-by-side 95% confidence interval error bar is made based upon the assumption that they're independent, which is not really correct for the paired samples. So we will talk about this in more detail later on.
So it looks like there is some difference between these means but before we look at the paired sample t test result, we want to take a look at the normality test result with the Shapiro-Wilk. So the baseline minus treated you have W statistics and the associated P value which is 0. 16.
So when you compare this against alpha 0. 05 that means we because the P-value is greater than alpha 0. 05 that means we fail to reject the null of no difference.
In other words, the difference data set is not statistically different from normal distribution, so more or less normally distributed. So now we can take a look at the paired samples t-test result. So the order of subtraction goes like this baseline minus treated.
So this order of subtraction is very important. Depending upon the order of subtraction, we will get either positive statistics or negative statistics and you want to make sure that the sign actually goes well with the the order of subtraction. So we assume that the baseline should be larger than the treated right so it is expected that the drug should reduce the treated PWV against baseline.
So this is large and this is small so if you subtract small from large then you should get positive value. If you have negative value then there's something wrong. So you always have to make sure that if the outcome statistics, the result is in the right direction always.
So it is in the right direction at least because we have positive statistics and mean difference is also positive. It should be. The degrees of freedom is 17.
So for a paired sample t test the degrees of freedom is n minus 1. So here the n is the number of pairs. In our case, it's 18 pairs.
So 18 minus 1 should be 17 and P is quite small and so it's way less than . 05. That means this mean difference is statistically significant.
So this is the mean difference and the 95% confidence interval around this mean difference is this. The lower boundary is 2. 6 and upper boundary is 5.
2 and 3. 9 should be somewhere in the middle. And because the both boundaries of 95% confidence interval are positive, we know that this difference is positively significant in terms of statistics.
So the mean difference is a positively great, meaning so that that is actually a supporting evidence for the alternative hypothesis. We expect that the drug should reduce the PWV of the patients so we can say that the drug is effective at least statistically speaking. I don't know if you remember what I said about the within subject design compared to the between subject design before but I said that the within subject comparison or within subject design is supposed to be more sensitive to find the difference because the groups or conditions being compared in within subject design are related.
So each individual in each condition, they act as their own control. So in effect, the subject-to- subject variability is supposed to be minimised in theory for paired samples design. In other words, within-subject design should reduce the extra amount of between-subject variations present in individual subjects across the conditions being compared, namely baseline and treated in this case.
The design should give us more sensitivity in the data which typically results in a small error bar compared to the between-subject design. But unfortunately this is not done automatically by many statistical software including Jamovi. So we need to take this into account by adjusting the extra variability manually, which was first suggested by Lotus and Mason in 1994.
So let's see how we can do this in Jamovi. Now we're back to Jamovi and let's see how we can adjust the size of these 95% confidence interval according to the paired samples. So let's go back to data and then the first thing you need to do is to create an average column between baseline and treated.
So click on c and then it should be new computed variable sp it just moved to. . .
I'll just delete this. and then I'll just name it as average and it should be the average between these two columns. So baseline plus treated divided by two will give you the average column.
Now that you have this average column created, you want to have average of the average which is grand average. So just get the descriptive of the average column all you need is mean. Move average to the variable to get the average, so 10.
486 so that is a grand average. Now you go back to data and create another computed variable to subtract the average from the grand average so this is adjustment so here the idea is that you would like to actually adjust the amount of variability that is common (shared) to both conditions baseline and treated because this is paired. So the variability created in this graph is actually overestimated.
So you'd like to actually make the appropriate adjustment and so here you subtract the average column from the grand average so that's average you do that and then these numbers represent the amount of adjustment should be applied to each baseline and treated condition. So let's start with. .
. the baseline adjustment, so all you have to do is to adjusted baseline, move baseline and add the adjustment to make the adjusted baseline PWV and you do the same for treated adjusted treated So you add the adjustment to the treated column. Great.
So this is it. Now you can re-plot the side-by-side 95% confidence interval using these two columns. So these columns are created only for the visualisation purposes.
You are not running the paired samples t-test on these adjusted values. You should use the original scores to test the paired samples, to run the paired samples t test, not on these two columns. You only use these two columns to create new side-by-side 95% confidence interval.
Now we go back to analysis t-test paired samples t-test now because we already run the t-test we don't need that all we need is just a descriptive plot right and you move these two last two adjusted values together to the right pane and then here we have newly created side by side 95% confidence interval and see if you can. . .
if you compare these two there is obvious difference actually created. So here I put them side by side so the left one is what Jamovi automatically created as if these two conditions are independent and the right one is after we adjusted the error bars taking account into the design component. So as you can see, we have a lot more separation between these two error bars on the right and also the size of the arrow bar decreases which is supposedly closer to the true difference between the paired samples and even though our column headings in Jamovi says adjusted baseline and adjusted treated, you will present this as just a baseline and treated.
So you do not have to use the adjusted namings because these are the correct error bars for each condition. So this is basically how you create a within-subject error bar using Jamovi so make sure that you do this when you have paired samples if you ran the paired samples t-test to compare the difference.